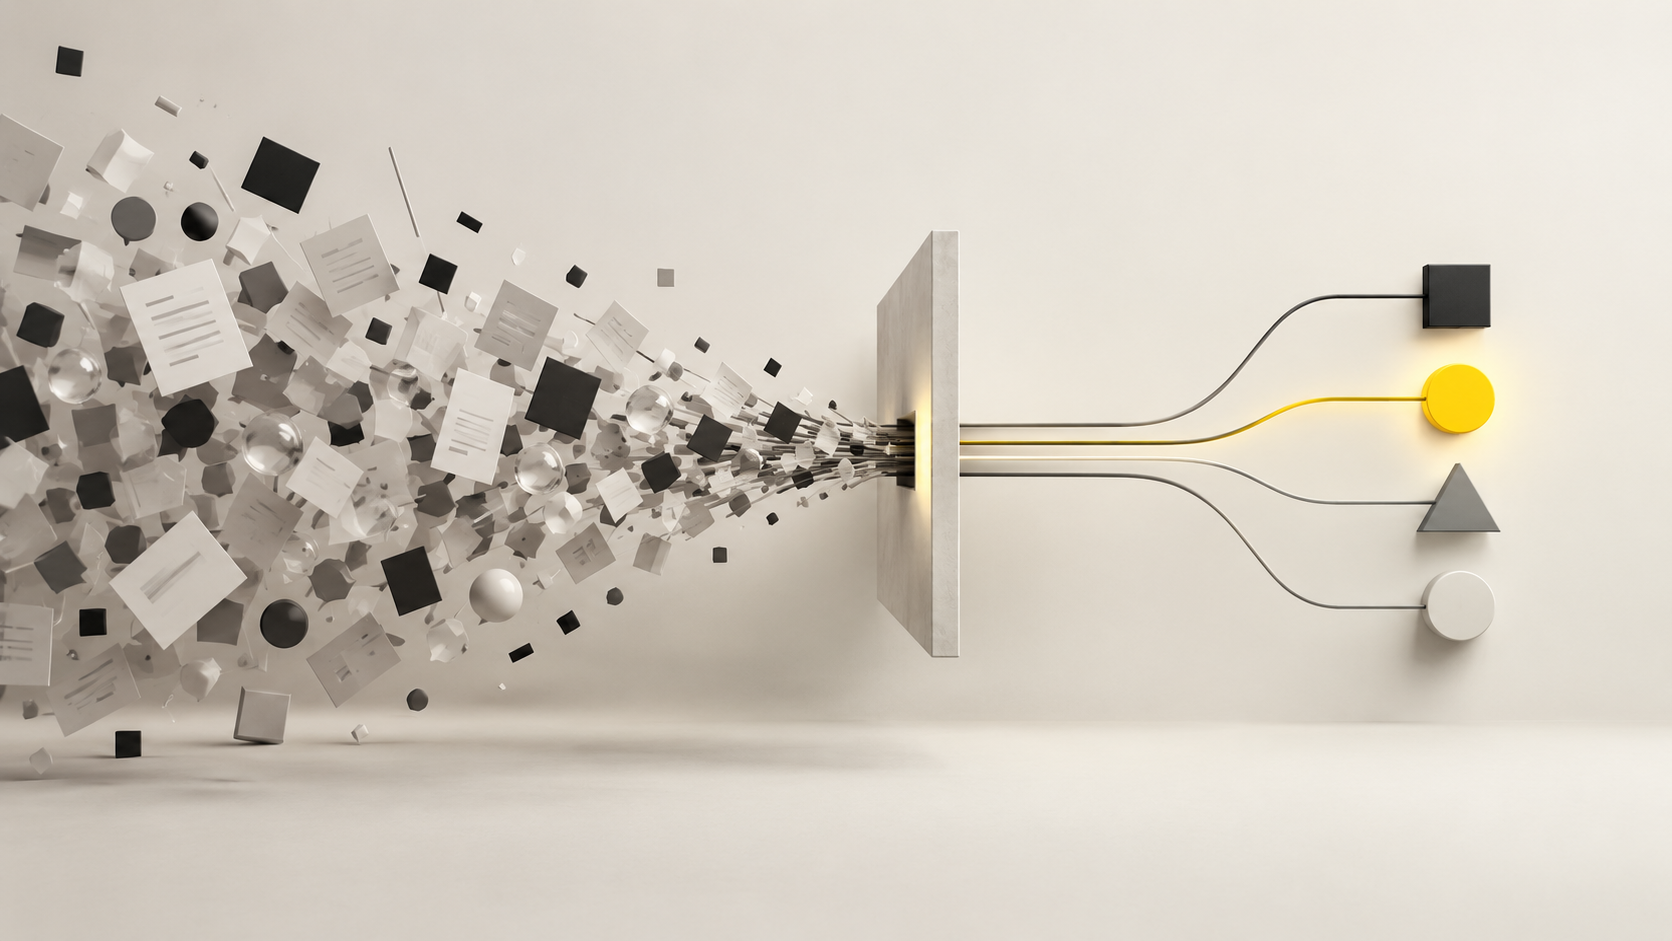
Most of the industry has spent several years making models better at generating things. Better answers, better code, better images, better reasoning, better conversation.
TypeSafe AI is taking a different route.
Its first model, Jev, is not primarily designed to produce language for a person to read. It is designed to take unstructured information and return structured decisions that software can use.
That sounds like a technical distinction.
It may turn out to be a commercial one.
yellow3 Lab received access to TypeSafe before its public launch. On 17 September 2026, we tested Jev 1.13.0 through the company’s authenticated Playground using synthetic business situations.
The investigation was small and it was not a benchmark. It was enough to show what is interesting about the approach, and where the harder questions begin.
From the research behind ChatGPT to a different kind of model
TypeSafe is co-founded by Diogo Almeida, Erik Gafni and Sasha Sheng. Almeida co-authored the 2022 InstructGPT research, which showed how human feedback could make large language models substantially better at following instructions. That work became part of the development path toward conversational systems such as ChatGPT.
The company is now pursuing a different idea.
It calls Jev a System One model. Instead of producing an open-ended string of text, Jev receives information and a set of permitted decisions, then returns structured answers together with probabilities and confidence information.
TypeSafe describes this as turning unstructured state into typed probabilistic decisions.
TypeSafe’s introduction to Jev
The distinction matters because a great deal of business work is not a writing problem.
It is a decision problem.
Where should this request go? How urgent is it? Is important information missing? Should software continue automatically, or should a person intervene? What happens next?
Those decisions run constantly inside a business, usually before any visible work begins.
A problem a business could actually have
Consider a customer whose payment connection keeps failing. Orders are being lost and they want it fixed immediately.
Before the business can respond, four decisions have to happen: which team receives the issue, how urgent it is, whether a person should step in, and what happens next.
We asked Jev all four together.
It routed the issue to the technical team, assigned the highest urgency on our scale, estimated a 92% probability that immediate human intervention was required, and selected human review as the next action.
The answer was not absolute. Jev also gave the billing team a 26% routing probability, recognising that a payment problem could plausibly belong there.
That residual uncertainty is part of the output, not a flaw in it.
In a real application those answers could become inputs to a workflow. Route the ticket. Flag the incident. Escalate. Ask a person to intervene.
Jev performed none of those actions in our test. It produced the decisions an application could use to decide whether to perform them.
Then we removed some of the certainty
Real business information is rarely clean, so we changed the situation.
The customer was now unsure whether the problem was a failed payment connection or an unpaid invoice.
Jev changed its response.
Rather than committing to the earlier action, it chose to gather more information, and its urgency assessment divided evenly between the two possibilities on our scale.
When we supplied a further update confirming the incident had been resolved, it moved again. Urgency fell, as did the probability that someone needed to intervene.
None of this establishes how Jev would perform across thousands of real cases.
It does illustrate the product idea.
The model is not being asked to write a convincing explanation of what should happen.
It is being asked to decide.
105 answers, at a median reported 96 milliseconds
Across the investigation we collected 19 responses containing 105 individual answers.
The median evaluation time reported by the TypeSafe service was approximately 96 milliseconds.
That number needs a qualification. It is the evaluation time reported by the product, not a measurement of the complete path from a person clicking a button to a result appearing on screen.
Even so, speed sits at the centre of the proposition.
A model embedded deep inside ordinary software may be called repeatedly. One customer interaction could require several decisions. An automated process could require hundreds or thousands.
At that volume, fractions of a second start to matter.
So does cost.
Applying the input-token price shown in the TypeSafe console to our recorded usage, we estimate the model cost of the entire investigation at less than one-tenth of one US cent.
That is not the cost of operating an automated business process. Infrastructure, engineering, integration, monitoring, failures and human involvement all still exist.
It is an estimate of the model cost represented by our test, and nothing more.
But the economics become interesting if useful decisions can genuinely be made both very fast and extremely cheaply.
Intelligence then becomes something software can afford to call far more often than it does today.
“Cannot hallucinate” needs a precise definition
TypeSafe makes a strong claim about Jev.
It says the model cannot hallucinate.
In the company’s own explanation, the claim is tied to Jev’s restricted output structure. The permitted answers are defined in advance and the model selects among them. It cannot invent an output that violates the expected type.
That is a real property and a useful one.
Structural validity, however, is not factual or semantic correctness.
A model can return a perfectly valid answer and still return the wrong one.
We tested that boundary deliberately by building a routing question in which the correct team was absent from the available choices.
Jev still selected one of the teams we had provided, and did so with high confidence.
We then added “none of the above” as an option.
Jev selected it.
This was an impossible question by design and says nothing about Jev’s normal error rate.
It demonstrates something more fundamental: constraining what an AI is allowed to say does not guarantee that the correct answer is among the choices.
The responsibility for the decision environment stays with the people designing the system.
If uncertainty is possible, the workflow needs somewhere for uncertainty to go. If none of the available answers may be correct, the model needs permission to say so. If a wrong decision is expensive, the software needs an escalation boundary.
Type safety does not remove system design.
It makes system design more important.
Structured answers alone are not enough
There is a second reason TypeSafe will need evidence.
General-purpose AI models can already be constrained to return structured output. OpenAI, Anthropic and Google all provide mechanisms for producing responses that conform to predefined schemas.
OpenAI Structured Outputs
Anthropic Structured Outputs
Google Gemini Structured Outputs
That means the case for Jev cannot simply be that it produces answers software can parse.
Other models can already do that.
The consequential question is whether a model designed specifically for decisions can deliver a better combination of accuracy, calibration, speed and cost.
TypeSafe publishes its own workflow evaluations reporting large speed and cost advantages for Jev on System One tasks. Those are company evaluations, and TypeSafe itself documents limitations and possible sources of bias.
Our investigation included no matched benchmark against competing models, so we cannot independently establish those comparative claims.
That is precisely the comparison that now becomes interesting.
The bigger idea may matter more than Jev itself
The AI market is often discussed as though models were competing to become one universal intelligence layer.
The better question may eventually be which model should do which job.
One model when a person needs to reason through a difficult problem. Another when software needs to generate code. Another when a business needs language. Another when a system simply needs to make a tightly bounded decision in 100 milliseconds.
If that is where this goes, “which AI model does your business use?” becomes the wrong question.
The questions become: what decision are we making, how expensive is a mistake, how fast must it happen, how much uncertainty can the surrounding system tolerate, and at what point must a human take over?
That turns model selection from a leaderboard exercise into an operating decision.
Why we are watching Jev
Our early investigation does not establish that Jev is better than a general-purpose model.
It was never designed to.
What it establishes is that TypeSafe has built a working product around an important idea.
Language models showed that machines could become extraordinarily capable at understanding and generating language.
TypeSafe is asking what happens when some of that capability is rebuilt around decisions rather than sentences.
Jev gave useful answers in our scenarios. Its reported evaluation times were fast. Its estimated model cost in our test was very low.
And our deliberately impossible question exposed a boundary that matters: even a perfectly constrained output can still be the wrong decision.
That combination makes Jev worth investigating further.
Not because another AI model has arrived.
Because it points toward a market in which businesses stop asking for the single smartest model and start assembling intelligence around the particular work that needs doing.
That is the perspective behind yellow3 Model Intelligence.
We examine model capability alongside adoption, economics and real-world behaviour, because organisations choosing AI need more than launch claims and leaderboard positions.
Early access gives us something new to investigate.
Testing gives us something concrete to say.
Explore yellow3 Model Intelligence
Research note: yellow3 Lab tested Jev 1.13.0 through TypeSafe’s authenticated Playground on 17 September 2026 using synthetic business scenarios. This was a small exploratory evaluation, not a comprehensive benchmark. The pre-launch invitation and subsequent testing were separate events. Inputs and full responses were retained for review.